Tracking prices for a few dozen competing products can still be done manually. However, as soon as the product lineup includes several thousand SKUs, prices change frequently, and multiple retailers or marketplaces need to be monitored, this method quickly reaches its limits. Teams then end up spending a significant portion of their time searching for prices, verifying product matches, and consolidating files that may be outdated even before they’re analyzed.
The price scraping, or price scraping, automates this data collection from e-commerce sites. It allows companies to monitor competitors’ offers more regularly and provides a factual basis for analyzing their market positioning. However, the sheer volume of data collected does not guarantee its value. A price is only useful if the product is correctly identified, if the promotion and availability are understood, and if the information can be linked to a pricing decision.
The question, therefore, is not just how to collect competitors’ prices. It is necessary to determine which data to track, how to ensure its reliability, and how to transform it into actionable metrics without automatically aligning one’s prices with the lowest offers.
What is price scraping?
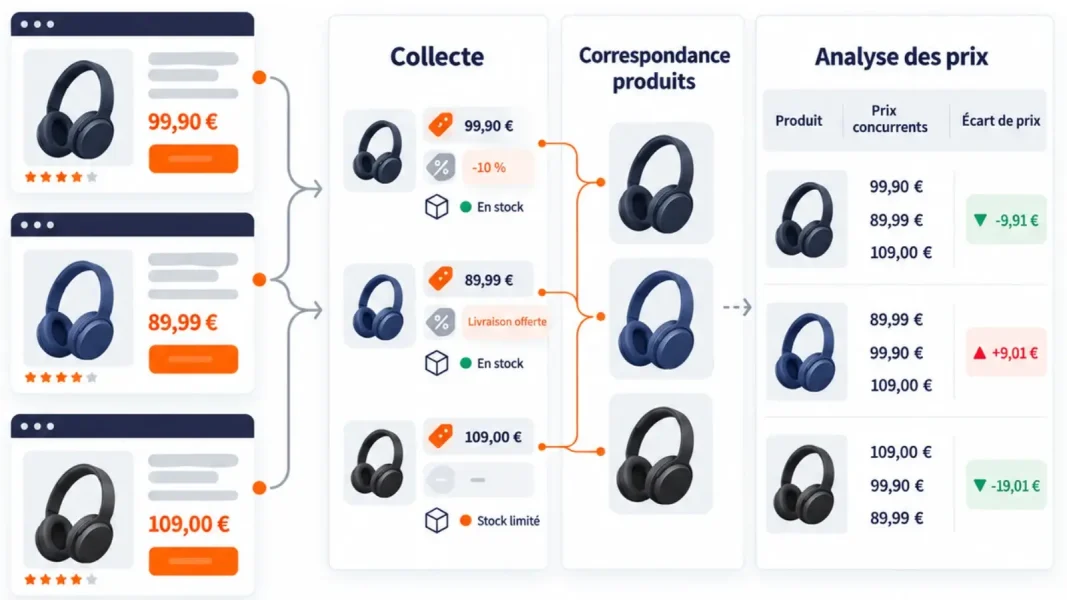
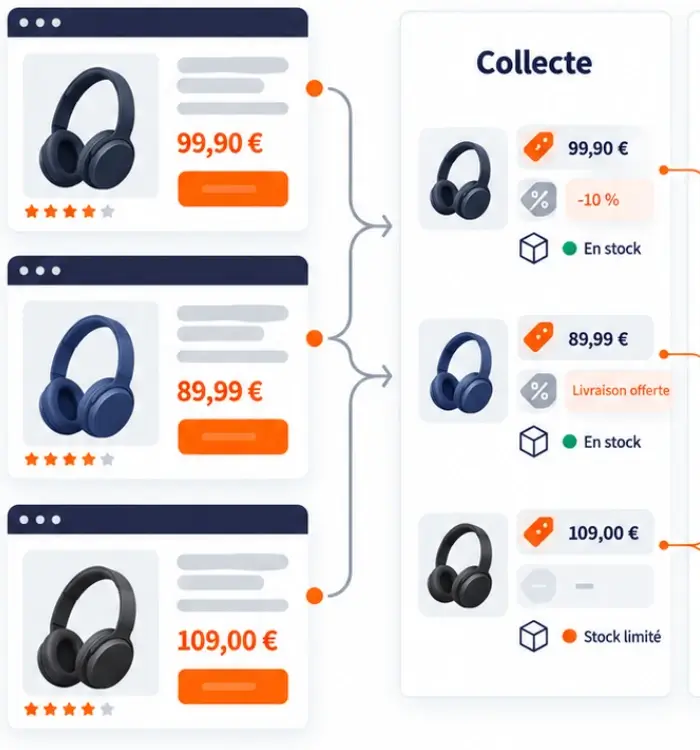
Price scraping is a technique for automatically extracting pricing information published on web pages. A program scans the selected URLs, identifies the relevant fields, extracts their content, and then outputs the data in a structured format.
The data collection may include, among other things:
- the list price, the discounted price, and the strikethrough price;
- the amount or percentage of a promotion;
- offers available exclusively to members of a loyalty program;
- promotional codes, coupons, prize packages, and bundles;
- shipping costs and terms;
- product availability;
- a seller on a marketplace;
- the timestamp for each reading.
Unlike search engines, which index content to respond to search queries, a scraping tool extracts defined fields from targeted websites. It does not aim to Search Engine Optimization : It consists of structured data that feeds a competitive intelligence.
Why is price scraping important?
Why Should You Track Your Competitors’ Prices? Price price scraping enables retailers to gain a consistent and structured overview of their competitors’ prices. On a large scale, it becomes possible to track more product SKUs, retailers, and channels than with manual monitoring, but above all, to detect market trends: price drops, new promotions, changes in positioning, or the emergence of a competing product.
This data is then used to analyze price competitiveness. In particular, they make it possible to calculate a price index, measure gaps relative to competitors, and track how these gaps change over time. The competitive benchmark can also be refined by category, brand, geographic region, channel, or the product’s role in the product mix.
However, not every detected price change should automatically result in a price adjustment. A price drop on a highly visible and directly comparable product does not have the same impact as a one-time discount on a secondary SKU. By cross-referencing data from web scraping with sales figures, price elasticity, inventory levels, and margins, retailers can better prioritize the discrepancies that truly require action.
The goal, therefore, is not to systematically match the prices of the cheapest competitor. Such a strategy could fuel a price war and erode profitability. The price competitiveness is more about determining which products to price aggressively, which to price in line with the market, and where to maintain higher margins.
Before implementing a new pricing strategy, simulation allows you to assess its potential impact on sales, margins, or the price index. Monitoring the results then allows you to adjust your decisions. Price scraping thus becomes a a source of information to support pricing strategy, rather than simply a mechanism for aligning with the competition.

How does price scraping work?
A price scraping project begins with defining a specific scope: competitors’ websites, categories, SKUs, geographic areas, channels, and collection frequency. Trying to monitor everything mainly results in a large volume of data that is difficult to analyze. The choice of sources and products must therefore meet specific needs: tracking SKUs that influence price perception, monitoring promotions, identifying the arrival of new competitors, or measuring discrepancies within a priority category.
Once this scope has been defined, the crawler scans the selected pages and extracts the desired information. Currencies, units of measurement, dates, and promotional terms are then standardized to facilitate comparisons. Checks are also performed to identify missing data, unusual variations, or changes to the structure of the websites.
The frequency of data collection depends on the industry and the rate at which prices change. For some categories, daily data collection is sufficient. Others, which are subject to more rapid fluctuations, require a monitoring more regularly. If readings are taken too infrequently, significant changes may be missed. Conversely, increasing the frequency of data collection without a specific need increases data volume and costs without adding value to the analysis.
The data is stored over time and displayed in a dashboard, in the form of indicators or alerts built into pricing tools. This historical data makes it possible to distinguish between a one-time fluctuation and a more sustained trend, as well as to measure the actual duration of a promotion.
Price Scraping: Product Matching—The Key to Reliable Price Data
Price scraping allows you to collect prices listed on competitors’ websites on a large scale. But simply retrieving a price isn’t enough: you also need to know which product it corresponds to and ensure that the comparison is based on items that are truly comparable. That is precisely the role of product matching, a critical step in ensuring the reliability of price scraping.
When the EAN is available and matches, the matching process is relatively simple. But in practice, many product listings do not display it, product names differ from one website to another, and some retailers offer specific formats or product codes. Data obtained through price scraping must therefore be matched based on several attributes: brand, product name, volume, format, ingredients, color, scent, model, or technical specifications.
Matching algorithms can analyze this information, suggest matches between the collected products, and assign a confidence score. However, it must be possible to review ambiguous cases. For example, a 1.25-liter bottle should not be automatically matched to a 1.5-liter size simply because the brand and fragrance are identical. The price per liter can facilitate the analysis, without necessarily making the two items strictly equivalent.
The quality of a price-scraping tool therefore depends as much on its ability to collect data as on the accuracy with which products are identified and matched. Poor matching can skew competitive analysis, generate false price alerts, and lead to unjustified repricing decisions.
Performance should therefore not be evaluated solely based on the number of pages or prices scraped. Coverage rates, matching rates, the confidence level of matches, and the speed at which anomalies are processed are also essential for a truly actionable price monitoring system.
What data should be collected in addition to price?
The listed price represents only part of the offer. To conduct a competitive analysis , it is also necessary to take into account promotional offers, availability, the seller, the sales channel, and when the price was raised.
Not all promotions can be compared in the same way. An immediate discount, a loyalty benefit, a deferred coupon, or a bundle offer each have different terms and conditions. The reference price must therefore be used to determine the actual discount offered to the customer.
Availability also plays a key role. The price of a product that is out of stock does not exert the same competitive pressure as that of an item that is immediately available. Matching the price of an unavailable product can therefore reduce margins without generating additional sales.
The analysis must also identify the seller, the channel, and the geographic area in question. On a marketplace, the price may be set by a third-party seller. It may also vary between the website and the physical store, or from one location to another. Comparing these offers without putting them into context is like comparing commercial situations that are not equivalent.
Finally, each inventory count must be precisely time-stamped, since prices, inventory levels, and promotions do not always change at the same rate. Maintaining a historical record makes it possible to track the frequency of changes and assess the stability of the competitive positioning and to distinguish a one-time event from a more lasting trend.
What are the limitations of price scraping?
Websites modify their pages, load certain content dynamically, or display different information depending on the user’s location. A field may disappear even though the price has not actually ceased to exist. The system must therefore be monitored and corrected.
The second limitation relates to scope. The web does not necessarily reflect in-store prices, merchandising, out-of-stock items, or local promotions. For an omnichannel retailer, field surveys remain a complement to online data scraping. Consolidating these two sources avoids the need to build the benchmarking based on a partial view of the market.
Millions of data points cannot compensate for either uncertain matching or a poor definition of relevant competitors. Without prioritization, teams can no longer distinguish a technical anomaly from a significant trend.
Finally, data collection must comply with the rules applicable to the sources consulted, data protection requirements, and access conditions. These practices must be governed at the technical, contractual, and legal levels. This governance is as much a part of the project as the effectiveness of data collection.

Price Scraping: Which Solution Should You Use?
The choice depends less on the theoretical volume of data than on internal capabilities, the expected level of customization, and the end use.
A standalone tool is suitable for organizations that have technical expertise and want to manage their data collectors. It offers flexibility, but the company is responsible for maintenance, standardization, storage, quality control, and often data matching.
An agency can design and maintain a customized system. It is important to specify what the service covers: data collection, incidents, product reconciliation, history, data retrieval, timeframes for restoring service, and data ownership. A price list alone does not constitute a decision-support tool.
A specialized platform typically combines data collection, matching, quality controls, historical data, metrics, and integration with pricing processes. It is designed for long-term use by multiple teams. Its value depends on its ability to identify the right discrepancies, not just a large volume of prices.
To compare the options, six criteria are key:
- coverage of signs, channels, and service areas;
- the reliability of matching and the handling of ambiguous cases;
- taking into account promotions, inventory, salespeople, and expenses;
- data freshness and incident management;
- integration with analytics tools and pricing workflows;
- the total cost, including maintenance, inspections, and staff deployment.
So the best solution isn’t necessarily the one that collects the most. It is the one that provides data that is reliable, up-to-date, and contextualized enough to support priority decisions.
How can you turn data into pricing decisions?
The project must begin with business-related questions. For which products does the retailer want to maintain its price image? Which direct competitors Do they actually influence their customers? What discrepancies require an alert? How much leeway is there before a rate needs to be adjusted?
These questions determine the scope, frequency, and level of detail. The results must then be linked to sales, margins, inventory, elasticity, promotions, and product segments. The significance of a variance depends on the volume sold, demand, and the role of the SKU.
Management can rely on a few indicators: price index, percentage of cheaper or more expensive products, magnitude of price differences, matching coverage, and frequency of changes. The analytical tools must link the summary to the references that explain the result.
Alerts should be prioritized based on their potential impact. Instead of flagging every variation, the system can identify sustained trends, high-visibility products, or deviations that exceed a defined threshold. Teams can then devote their time to analysis and decision-making rather than checking files.
A concrete example of price scraping
Let’s take the example of a retailer who wants to track the price of a package of coffee sold on its website and at five direct competitors. The system checks each product page several times a day and records the listed price, any promotions, the price per kilogram, availability, and shipping costs.
At 9 a.m., a competitor is offering the package for 5.90 euros. At 2 p.m., the same product appears for 4.90 euros. Taken on its own, this change might warrant an alert. A more thorough analysis shows, however, that the second price is reserved for members, that you must purchase two units, and that the product is no longer available for delivery in several areas.
This example illustrates the difference between extracting a number and interpreting an offer. If the data collected is limited to the price of 4.90 euros, the retailer risks comparing two different commercial offers and unnecessarily lowering its price. Meaningful data collection must preserve the context that gives the information its meaning.
The same logic applies to a marketplace. A single listing may include multiple sellers, each with their own price, inventory, shipping costs, and delivery times. The price displayed at the time of the check is not always that of the monitored retailer or the offer actually available to all customers.
From Automated Data Collection to Price Performance Management
When prices change frequently across thousands of products and multiple channels, manual monitoring no longer provides a comprehensive or up-to-date view. Price scraping addresses this limitation by automating data collection, but simply scanning more pages is not enough to improve pricing decisions.
The reliability of market monitoring depends first and foremost on the quality of the product matches. Each offer must then be placed in its proper context: promotion, availability, seller, channel, geographic area, and time of data collection. Historical data helps distinguish between a one-time fluctuation and a more lasting change, while in-store surveys supplement information that is not available online.
The goal, therefore, is not to react to every move made by competitors. Rather, it is to identify discrepancies that warrant special attention and then assess their potential impact on sales, price perception, and margins. Price scraping provides the signal; the quality of the matching, analysis, and simulation make it possible to determine whether to adjust a price, maintain its positioning, or take no action.